Transcript#
This transcript was generated automatically and may contain errors.
Hey there, welcome to the Paws at Data Science Hangout. I'm Libby Herron, and this is a recording of our weekly community call that happens every Thursday at 12pm US Eastern Time. If you are not joining us live, you miss out on the amazing chat that's going on. So find the link in the description where you can add our call to your calendar and come hang out with the most supportive, friendly, and funny data community you'll ever experience.
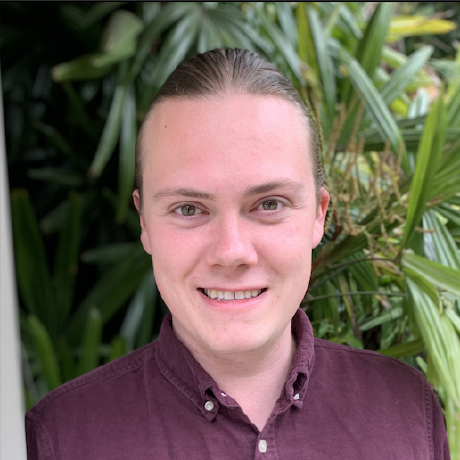
Can't wait to see you there. I would like to introduce our featured speaker for today, which is Max Kuhn, Principal Software Engineer for tidymodels here at Pawsit. And you probably know Max Kuhn from a lot of other things, and Talks He's Given, and the Carrot Package. Max, would you like to introduce yourself, tell us a little bit about what you do, and also something you like to do for fun?
Yeah, I'm a statistician. I worked in pharma and infectious disease diagnostics for like a long time before joining Pawsit. Fun fact, at one point, like the way, one of the ways I got the job was, I think Hadley and our owner JJ were talking, and they happened to be in New York City. And Hadley had had my number from like a previous user. And he texted me and said, hey, do you ever come down to New York City? And I was like, really? I actually had Hamilton tickets that day, and I was like three blocks away from them. So I literally was like, I'll meet you at the corner and so and so. And then we talked about modeling stuff. So that was kind of an interesting experience that eventually led to me joining the company.
Yeah, so I'm a statistician, started at Pawsit in 2016. So I'm coming up in November, I think on 10 years. And I've mostly been concerned with various types of modeling activities, like a lot of data analysis, and visualization stuff, but modeling and data analysis is really where it's at for me.
And I will say, the first time I ever heard your name, or read your name, I guess, was when I was using the carrot package and learning the carrot package. And I feel like a lot of people their introduction to you as a person was probably carrot. So I'm gonna put a poll in zoom, if anybody would like to, to answer that, have you use the carrot package, but also Isabella is usually the one who does zoom polls. So I don't know if I did it right.
Can anybody see the poll in zoom? I usually do them in Slido, but I wanted to test it in zoom this time. Okay. Anyway, we will see if that gets answered. And if I can actually see the answers to it in a second. But can you tell us a little bit about it? Yeah, let me. Why? I don't like this. Does it work now? Zoom's the worst. I don't see it. Well, you guys, that's okay. Oh, there it is. I did it. Okay. Okay. Well, lesson learned Slido is way easier for polls y'all, but not everybody has hopped onto Slido. So often zoom is the more accessible thing.
Okay. Enough of me talking. That's my selfish question to you, Max. Can you tell us about carrot and how it came about and where it falls in the timeline of you joining Posit?
Origins of the caret package
Yeah. So I think it was like around, so I started, so I worked in drug discovery, like early drug discovery at Pfizer. And I think I started there in 2005. And a couple of years before that, I had been working in infectious disease diagnostics and we had a big, like, it was kind of impressive for the, for the time it was at, but a big, like a clinical trial based project to work on predicting sepsis, which is pretty serious and kind of hard to predict. And so we'd been doing a lot of like machine learning, like wide dataset machine learning. And it just occurred to us that like, we don't have a lot of like basic helpers for things like computing sensitivity and specificity. And so I thought I should make a package out of this.
And then I left there and went to Pfizer. And the thing about most big corporations is like, you start there and then like maybe like 80 help desk tickets later, you actually get access to data. So they like day one, bring me this nice laptop, but I can't, I'm going to meetings, but I can't actually do anything. Cause there's no, there's no data. So I decided to just start this R package, which actually had a different name when I started. And I was going to be using it a lot for my job. So I just started writing it. I was doing a lot of computational chemistry stuff then. And yeah, it just sort of evolved.
And then when it's like a year or two later, when I finally sent it to CRAN, I think like not long before somebody had used the same package name. So I had to come up with something sort of like at the last minute and landed on Carrot. So yeah, so that's how that came to be. It was maybe like, I think maybe the first CRAN version was maybe like 2007 ish, I think. Okay. So long before you joined Deposit.
Yeah, that was pretty far before. And then, you know, once I started working on tidymodels, there wasn't honestly a lot of time to work on it. So it's sort of like it didn't flounder, but I just wasn't really doing much development for it. Which I think frustrated a lot, frustrates or frustrated a lot of people. But funny enough this year with our internship program, we had sort of like a list of things people could work on in Charlotte, our current intern decided she wanted to work on Carrot. So if you go there and look at like the contribution graph, there's like this big, like no man's land where like nothing really happened. And then it's like a huge amount of contributions now. So we're just like cleaning it up.
Yeah, it's hard to believe this package was written before or had like named spaces before Knitter, like way before like Knitter and things that we just like, it's hard to believe that that was still the case, but so we need a lot of modernization. Oh yeah, yeah, yeah. So, so we're just basically bringing it up to like where things are at today and just improve it in terms of just keeping it sustainable. So yeah.
From caret to tidymodels
Well, part of the goal of just keeping it sustainable is because there is a new wear option, right? Cause we now have tidy models. Do you want to talk a little bit about how tidy models came about and why, why new tidy models instead of just updating or modernizing Carrot?
Yeah. So, so Carrot, okay. So like, you know, I learned some, I'm a statistician, right. And we're not known for our like exquisite software engineering skills. And I had learned a fair amount in graduate school. And then that first job I had in diagnostics learned a lot there, but Carrot was something that I sort of did a bit in my spare time. And so it did not, it was not like something where I thought out like, oh, we'll do, here's all the things that are going to be on the menu. It sort of grew and grew and grew. And I didn't expect anybody to use it, but then they started using it. And then I was like, sure, let's add this. And it just like became kind of a monster to maintain because for both me and for Crayon, to be honest with you.
So it, it has a very traditional like base or type interface and people, you know, a lot of people like that. So I didn't want to like tidy that and just make people use that. And re-engineering it, like for survival analysis, like an example where it was very, very difficult to include survival models in that package, just because of how it was set up. And, you know, with tidy models, it's more tidy interface. It's we, for better, for worse, make a lot more modular packages. So the idea was to have like a parallel implementation, somewhat kind of driven by like, well, if you like tidy-verse stuff, then you're going to look at Carrot and be like, oof. But then if you're more of a base R person that you would look at tidy models and not like that.
So it's just, it's, it's more enabling in tidy models to make new stuff. And it would be incredibly well pre-clawed and things like that. It'd be very, very difficult to really expand Carrot in the same way. So yeah. Totally understandable.
Well, there's some praise in the chat. Santiago says the ergonomics of tidy models is so much nicer than scikit-learn. And I agree. It's so baiting me. I'm like, don't, no, Max, don't, don't rant.
Thank you for the kind words though. And honestly, just about that, like, you know, we think about that a lot. Like the book I'm writing now, I'm writing like both like R and Python companions to it. And I have, I've stopped and started on the Python companion a couple of times because I feel like there's like a lot of basic stuff that's just like super hard to do in Python. And so, you know, Emil and our group who may or may not be here, we've been talking about like a recipes type version for Python. And so like we're, I think we are going to be chipping away at things. At least we find friction on the scikit-learn side.
So that's exciting. There's a lot of good things about scikit-learn. So I'm not like down with it or anything like that. But as somebody who did like modeling and machine learning for a living, I feel like you, you have a very different perspective than people who develop like software things who like haven't lived through that.
But as somebody who did like modeling and machine learning for a living, I feel like you, you have a very different perspective than people who develop like software things who like haven't lived through that.
So absolutely. Yeah. Well, speaking of Emil, Emil is not here, but if you know who Emil is, you know that he not only works on tidymodels and all kinds of stuff with Max, but he also on the side kind of just creates prolifically Quarto slide extensions to make slide crafting as he calls it in Quarto, using the reveal JS output better. And he is hosting a workshop. I think it's like a two hour workshop. You should go check it out. I am going to put the link to it in the chat right here. It's pos.it slash slide dash workshop, but it's abbreviated.
If you're available to attend that and you want more Emil in your life, go check that out. Okay. I might go to it, to be honest with you. You should. I'll be there for the first five minutes. I mean, every, we all need it. Yeah. Yeah. It's good. Yes. It's amazing. And also we will have Emil back on the data science lab to talk more about slide crafting very soon. He's climbing the leaderboard as repeat guest on the data science lab, because we just love having him so much.
Book on applied machine learning for tabular data
Okay. Let's hop over to Slido because you mentioned your book and Morgana had a question about just that. Morgana, would you like to ask your question?
Yes. Thanks Libby. My question was about books. So I know that you've written a number of books in the past about feature engineering and other topics that are similar. Are you working on anything right now?
Yes. Let me get the link for it. So we were going to write a second edition to apply predictive modeling. And it's mostly, I think, logistical reasons why it didn't happen. We haven't had a great relationship with our publisher from the jump. And we kind of got waylaid for about two years about a second edition. And I don't know, Kel doesn't do this as much as, my coauthor Kel doesn't do this as much as I do, but I'll look into something and I'll write a little bit about it and just put a QMD file or whatever somewhere and just like squirrel it away. So kind of had like a lot of things sort of like geared up to do that.
So instead of the second edition, with neural networks becoming so prevalent now, I was hesitant to maybe use this nomenclature, but like tabular data modeling, which is a really weird way of saying like the things we would normally do anyway, is pretty common nomenclature. So it's applied machine learning for tabular data. And it's basically like what we would have done for a second edition. The problem, I mean, the good and bad of it is we're writing it out in the open. So as soon as we write it, it's there.
I don't know if this is bad news, but it's forward thinking it might be an issue where there's really no like boundaries on like page count with a website. So I've got like a bunch of PRs to put in because I finally finished locally like my neural network with like the foundational models and like modern neural networks and stuff like that. And that's probably gonna be like if it doesn't get edited down, we eventually make it a physical copy. That's gonna be like 50 pages at least. So yeah, when we have the time, we're just cranking away at things.
And I don't know, I feel pretty good about it. Quarto is really great. We're using ShinyLive for some things. And I don't know, that's been a very, I really enjoy having, like I'm not just gonna keep writing books in perpetuity, but I enjoy having like something that like forces me to do research and read and stuff like that and look at what's happening. So yeah, that's all on its way.
Awesome. Thank you, Morgana, for the question. And I wanted to go back to the poll that I fumbled through getting to work. Thank you. I think it was Sunday. It was like the launch button. It took me forever to find the launch button. Oh, maybe it was no tobacco.
Okay. So we have our poll, 47% said, yes, they have used the carrot package. So that's almost 50%, which is pretty great. And then 18% said, no, I haven't used it, but I do know what it is. And 35% said, no, I don't know what the carrot package is. So maybe we should let people know what the carrot package is. Carrot stands for classification and regression training, right? With the RE being regression. And it is a package that lets you do machine learning in R with all kinds of different packages as engines for the different types of models that you would like to use. That's my own basic Libby definition. Do you have a better definition for everybody?
No, that's pretty much it. It was like my general like package for like modeling infrastructure. Okay. So like performance metrics and resampling methods and stuff like that. It should have really been multiple packages at the time, but it wasn't. So yeah.
It's definitely a monster package and it lets you use all of these different, essentially back ends
models to power what you're doing. You're modeling. For example, you can use the random forest package for you're in a forest. You could also use several other random forest engines to do random forest, but it kind of gives you a almost modularized way of plugging and playing. Tidy models is even more modularized, I think, than carrot was or carrot is because it's still working package, but I wanted to make sure everybody knew was on even playing field hero as we were talking about carrot.
Fantastic. Let's head back over to Slido. And I wanted to pull in Frank because Frank asked a question about tab PFN, like the moment before you even mentioned tabular. So Frank Hull, if you are available to ask your question live, I have highlighted it in Slido. And let's see if we can find you to get you to unmute. Okay. Do we have a Frank? Frank, who is an alumni.
Oh, Frank. We'll ask it for you. It says, what do you think about the recent improvements in deep learning for tabular data, such as tab PFN, tab ICL, tab FM, et cetera, compared to like GBM or XGBoost? Feel free to ask me for, for, as I do not have video audio, I didn't read the last part of your question, Frank. Oh, sorry about that. Yeah. They're pretty, they're pretty impressive.
Deep learning for tabular data
You know, like the whole like dominance of boosting is always just bounced with the kind of bothered me because you can do just as well without, like, if you put a little bit of work into it, like you can get like a smaller model usually that does about as well. And then like these tabular models, this we're taking it to the next level. So just to give you a sense of like what this, these are is, I don't know, some, some point in time ago, like in the last, like 10 or 12 years some deep learning people figured out that basically you can approximate like Bayesian inference using like a sufficiently sophisticated neural network that has a few architectural like particulars to it. And so the idea is and so TabPFN was probably the first one of those.
And so what they do is they have this massive neural network that they train, but they don't train on any real data. They have a means to simulate like every possible sort of like tabular data scenario with different numbers of rows or columns or correlations, like things having smooth like connections to the outcome or things that look more like trees and things like that. So they can like really efficiently simulate. I think it's like the last training point, I suppose, like maybe like 250 million datasets. And so they, they train these really large neural networks on these synthetic datasets at once, and you basically get the finished product. And so when you put your data in much like LLMs do these days, what these models do is they take your, you don't really have training data because there's no real estimation that happens, but you give it your training set data and it's sort of like your prompt in an LLM. It gives it context so you can, so it can do better. It has this huge network that could do almost anything. And as soon as you give it your training data, it basically lets it funnel down to concentrate on the parts of the network that are most relevant. And so you basically get an immediate answer without any actual training. And they do very, very well. I've yet to see them really falter anywhere.
So I've just finished like writing like a boatload about this, which I haven't put on the website yet, but just to be honest with you, one thing, and I think I've talked to Frank about this specifically, but in talks and things like that, the thing that confounds me a little bit about this is they perform well in ways that I can't explain. So if you, I have a huge simulation system where I run on a bunch of models where like I give it like one or 10 or 50 just noise columns and a regular neural network just dies when you do it. I mean, this performance is tanks, but and like a tree would not, or GlimNet or something that has like feature selection built into it does not have a problem with that. And I can't explain why these very large neural networks, these tapbfn type models just blow through that successfully. They're incredibly resistant to things like that. And I literally spent like two days both by myself and Claude just trying to figure out how this works and have yet to really give a, like a good answer that I would think like, oh yeah, that's it.
They're incredibly resistant to things like that. And I literally spent like two days both by myself and Claude just trying to figure out how this works and have yet to really give a, like a good answer that I would think like, oh yeah, that's it.
So, so yeah, so they don't end up, Morgana, yeah, they don't really end up overfitting because there's no real fitting. As long as you have like, in some other experiments I've run, as long as you have like, but depending on the problem, maybe like 100 or 200 or 500 data points, the model is able to really focus in on like the weights and the neural network that are relevant for your dataset. So I've, I've yet to see them either under or overfit. They're not perfect, but and I should also say like of the three that Frank mentioned, so tapbfn is like the original and some of that's, so it's a, you know, it's open source in the sense that we have a Python and we built our interface to the Python package. So we can, we can run it, but they're a company and they have licenses and things like that. So, and I think they were maybe not bought necessarily, but sufficiently funded to kind of be like bought by SAP. So I think where these models are going is they're just going to get built into databases probably where you have some table of data and it can automatically like just take that data and build like a pretty fast and decently performant model to just fill in the blanks for any outcomes you have.
So tapbfn was sort of the original one, that's a proprietary model. TabICL, ICL stands for in-context learning. That's a, I believe like a completely open source model that has no license associated with it. And then the new one, which is also somewhat proprietary by Google's called tabfn, fm foundational model. And so while we just released a version of Brulé package that has like local torch model for tabICL. So if you don't want to have it like reticulate your way through things and want like a pure R, which to me is like the preferred way of doing it, we basically emulated all the Python code for tabICL. So that's all available. So you start to run it and you have to download like, I don't know, I think it's like a hundred megabytes or so of model files that are the pre-built models and then it works.
Well, and that brings me to tabfm, which is the Google one that just came out, which we're also looking at. It's model files all told, I think are like six gigabytes. So Google is sort of like, well, it's, I don't know, honestly, I don't want to speak bad about it, but it's like, I was just benchmarking on my laptop and it's, I don't know, I feel like it's not built for anything, but Google's hardware. In the sense that just me loading the model is like, if I'm just doing regression, it's like three gigabytes in memory right there. And then they really, these models. Not everybody has that big of a laptop either.
And all of these models are required to GPU. I mean, you could, for predicting a few things, use your CPU, but the memory just spikes. So it's a little bit unusual that you need actual like GPU hardware to run these things at all. So, so anyway, that's.
This is a big question. It's probably a huge topic and also a great topic for the data science lab, where we talk about technical stuff, do screen sharing. And so I'm hoping that Frank will join me at the data science lab, Isabella and myself to talk more about some of this tabular stuff. And so we can all learn about it together. If you're interested in that, keep an eye out on the schedule for the data science lab where we meet every Tuesday. And maybe you can learn a little bit with us about that from Frank. These are about a year old, but I put in the chat an R format talk I gave. Nice.
There's probably a decent just introduction to it. So, I mean, they're incredibly, incredibly like effective. And the only thing that was sort of holding me back a lot of times is the potential and I'm not like some pure like, like open source, like it's not open source, but like, you know, I, I don't want to have to worry about license keys or tokens and things like that. So I think I mostly concentrate now with tab ICL. Yeah. And that might be what we work on as well. If we learn in the lab for a sort of pure R version that will be more accessible and fully open source. Okay. Fantastic question. Thank you so much, Frank. I will talk to you later, Frank, about the data science lab that maybe isn't there.
You're on our list, man. They're relentless.
Day in the life and work-life rhythms
So we have a question from Natasha. This is a classic Natasha question. Thank you. Which is, what does a normal day or week look like for you, Max? Because you started out as a statistician, you were in the trenches doing what I would consider like field work in statistics, but you work in a completely different capacity now. What does your day look like?
Yeah, I'd say the only downside to my job right now is I almost never get new data, right? So I'm used to having like the treasure trove of really cool, like cutting edge new data, but like I don't get any new data. And my day to day is really kind of, you know, I've read interviews with UA and Jenny Bryan, and I think all of us have a very similar outlook on things is, I feel like it's healthy, but it may not sound like it in a way. But like a lot of us have kids. I have two older sons, but two younger stepdaughters. And like, we're kind of free to work when we want. So like Emil is on the West Coast in my group, I'm in Connecticut. So like East Coast of the US and then Hannah's in London. So we have this like Goldilocks zone between like 11 and one where we can actually in real time, like sort of like talk to each other. And so, you know, there are days where like I'll get up and do kids stuff or whatever I need to do, and then don't get to work till like 11 and then do a bunch of stuff and then kids go home at three. So then, you know, pause, and then maybe do work later that night just to get everything done. So maybe it's not great to be like working at night. But I don't know, it suits me in a lot of ways. Because I can work whenever I want.
Max, I work at night, every single day. And honestly, I'm a night owl. And just to be honest, my wife is not. So my wife is like, goes to bed early. And I'm like, well, I'm just don't want to sit around watching TV or something like that. So I'll either like, if I don't have a game I want to play or something like that, like if I'm not going out or going to do something. Yeah, I my best writing some of my best work is at night. It's really when my brain's fully like up and around. So but you know, luckily, with our company, and all being remote, we have a lot of flexibility in terms of where and when and how we work. So yeah, so yeah, when I listen, it's probably like a normal day if that thing exists. This summer, my kids are away at camps and things like that. So I have like a lot more time on my hands. So it's probably a little bit more conventional than it would normally be. Because I have less constraints of where I need to be and things like that. So yeah, I love it.
Well, I'm gonna put a question in the chat, which is, are you a night owl or or an early bird? And we'll stick some take some replies on there for me. Because I'm gonna upload some of these.
Max and I are clearly both night owls. I work at night all the time. So I will work in the sort of mid morning where I have a Goldilocks hour with the people that I work with as well. And then I will take basically a lunch break that is dinner break and have dinner with my husband, who's an extreme early bird. And then I work at night. And that suits me perfectly, because that's when my brain is awake and going. And I schedule emails for the next morning, or I'll schedule messages to Rachel, I'll be like, this is a scheduled message, because I don't want to send her something at 11 o'clock or midnight. But you know what gets me? Google Calendar invites, you can't schedule them for later. So I do a ton of Google Calendar invites, and they will just end up in people's inboxes as emails at midnight, probably Google fixes for me. Okay.
So yeah, I think that it's healthy. I think it's healthy to work within your energy bounds. Thank you, Natasha, for that fantastic question. I always love it.
Background in computational chemistry
I wanted to ask, we had an anonymous one that I would love to ask about your background. And it says, what type of computational chemistry did you work on? This person says, I came from the, oh, wow, that question just disappeared. There it is. I came from that space many years ago.
I have a need to quantum chemistry.
I have a need to quantum chemistry to be specific. Thank you for saying that out loud. I didn't do that. I know that I could even answer that. I know what quantum chemistry is. But yeah, so like a big pharma company, you know, they're, you have medicinal chemists who know what thing in your body they want to modify, like, make more of this protein or make less of this protein or do X, Y, and Z. And, and so most, most molecules you can write down as an equation, something like called a smile string, which is like connection of like carbons and oxygens and bonds and stuff like that. And so the way it works is, you know, you're working on something like I worked on GLP drugs, GLP-1 drugs for like a long time. And this is like, you know, maybe like 15 years ago. And so, you know, they'll come up with an idea for a compound that might be effective. And sometimes they send that off to synthesis, meaning somebody figures out how to make that, and then they can test it on cells and things like that. But before they do that, they kind of want to get a first pass at, oh, is this going to kill somebody? Is this going to work? Is it soluble? Like, can we make it in solution? And so we have a ton of these, these chemical formulas in existing laboratory tests. And one thing in computational chemistry is called quantitative
structure activity relationship models, QSAR. And that's where you basically get this like string of, of connections between molecules. You can then, oh, I don't do this. We have a lot of software to do this, to then turn those into predictors in a model. And then you, you may have like a dozen, or you may have like a million existing data points. And so it's constantly making models to make predictions on like dozens of things like drug-drug interactions, and so on, so that somebody can type in a molecule they're thinking about making, and they get an initial like dashboard of like, oh, here's what's good about it. Here's what's bad about it. Here's things that are similar to it that we already have, and so on.
So it was basically either, I didn't actually, like I was never on the hook for that many models, but around that time, we were building a whole like framework. It was kind of like pre like Shiny based on Java, where basically you can go in and, you know, point towards a data table in a, in a database somewhere, or upload some, some strings and say, predict these. And then you had a whole list of like, you know, random forest or, or whatnot. And so I, that's honestly why Carrot was built, because I knew we were going to be doing that in having a, like a, a menu of things to make predictions with. That was the original goal of that. And that's what, I don't know if it's that framework is still there now, but that was the original goal of that.
So it's, it's great because the, the people you work with are incredibly engaged. You usually have a ton of data. Once you get the hang of those types of models, they're not all the same, but you pretty much know where to focus and what not to focus on. The downside is kind of interesting because like, you know, I love working with medicinal chemists, but they're really, they're really paternal and maternal. They will have this like molecule that they think is going to be the one. And then they run it through your models and you give it like a, like a, like a risk of having, let's say, like liver injury of being like 10 or 20% is like, no, that's right. Yes. And then now they're like, you know, if you give them then like no risk at all they wouldn't question it. But now they're in your office being like, I'm going to submit this every week and see how much it changes. I'm like, okay.
Okay. And there were also times where we had to be sort of like the ambassadors because we had the biologists and the lab people who are running these, these assays, these laboratory tests to generate the results. And then the consumers of the models saying like, well, I don't think the noise should be as high on this, or why is it so high? And then having to mediate between them to say like, yeah, this is as good as it gets, or this could be improved, or just being the person to like, not, it wasn't, it wasn't like any sort of like toxic environment, but basically like a little bit of deescalating people to just set expectations about what models can do and so on. So much of statistics is communicating things to people and being an intercessor.
So much of statistics is communicating things to people and being an intercessor.
I totally understand. Well, if anybody is curious, ab initio means from first principles, so ab initio quantum chemistry. So says Wikipedia. chemistry. So says Wikipedia is based on the aim to solve the electronic Schrodinger equation. This is above my brain's pay grade, Max. So if anyone is curious, go read that Wikipedia article. I think it's pretty good, at least the first couple of paragraphs.
JoCo Cruise and audience questions
All right, fantastic. Thank you for that question. We have about 15, 17 minutes left. Let's see how many more of these questions we can get in here. And I want to throw a chaos one in there because we had an anonymous question that says, can you tell us about the Joko Cruz? I upvoted that one. Did you? Okay, I'll try to keep this. I'm going to try to keep all my answers max level brief, which means like 30 minutes at the least. Joko Cruz has been around for like, maybe like 16 years now. I've been on, no, it's probably more than that. I think 11 of them. And so Jonathan Colton, Joko is this musician who's most known for the theme song to the portal games, the yeah, a lot of you nodding. And so he started this cruise where he basically had a lot of authors, musicians and stuff that would come. And I think it was like in year five or six, we had the whole boat to ourselves. So there's like, I think now it's probably like about 2,500 people. And it's just a really eclectic set of like geek culture.
Like I've, I've literally helped some entertainer change a diaper on their newborn that my kids were like, that's my favorite podcast. Who, how did you, right? So like, you're in this situation where like people you might idolize are sitting around you, but you can't like nerd out and they have their, you know, they're, they're on vacation too. But it's, there's a great New York Times article about it a few years ago that I think encapsulates it pretty well. The downside is including this year, there've been four years where either our Posit slash our studios conferences and or work weeks have been the same week as the cruise. In fact, for two years a row, when we had conferences in San Diego, the boat left like the same week. And I literally was like, I could see it from my hotel room. So my friends are there, I'm talking to them, they're going and I'm like, literally waving goodbye to the boat from the hotel.
But if you're, if you're really into books, especially John Scalzi is a staple there. N.K. Jemisin has been like, pretty much anything you can imagine. I'm hoping to get Sanderson there one day. But yeah, it's, if you're into music, there's a lot of comedy. They even had like, like, like Close Up Magicians one year. Like it's kind of place where like, the knitting club is called Creative Stabbing. I went to a lock picking seminar. It's there's, it's an incredible, let alone like just going and being in the Caribbean or somewhere to just go outdoors and things like that.
Sounds amazing. It kind of sounds like work week for Posit because we had on our day where we had Life at Posit, we had our knitters all together. I am one of them as well. But we also had V doing lock picking. So I still have a lock picking kit that I went home with a plane, went home with on the plane. And I was thinking, they're going to stop me at security because I have a lock picking kit. Seriously, I can't do that. I love it. They're so difficult. Okay. Yeah. Well, thank you for asking about the Joko Cruz. I love it. Everybody should go listen to the Portal theme song Still Alive. If you have not heard it, but if you are a Portal fan, let me know in the chat.
Data sets and tidymodels resources
Okay, let's hop over to Slido again. And we're going to ask a very open ended one that I really like because you mentioned not having access to new data. So if you could analyze any data set in the world, what would it be? And what would you be looking for? Maybe people are wondering how they can send you real new data. Well, please do find a way. I don't know that I have an answer to that. I don't know. That's really interesting. I think my interest in data is more on structure and the weirdness of it all, as opposed to I want to be able to predict this one thing.
So I loved working on biological data sets, but they tend to be pretty, what's the right word? Not that many rows. You'll have tons and tons and tons of columns, but maybe 200 rows, which is problematic in a lot of ways. So I enjoy that. I don't know. I wouldn't be driven by subject area. I'd be more driven by the problems of that particular data set. I don't know. I feel like statisticians have this idea that we'll see papers that using neural networks in traffic prediction, well, they're just neural networks. We don't care what the data set is. We know they work. Why do you have a paper about this? So I tend to feel the same way. I don't really think much about the... Well, I think about the consequences when I'm doing it, but I'm not attracted to data sets based on they're for this or that. So yeah.
All right. Well, if you have novel or fun data sets that you want to send to me, I will get them to Max and we will make sure that he knows they're from you. Okay. We had a question from Zach that has an asterisk, so I'll ask it as well. It says, do you have any book recommendations for getting into machine learning using tidymodels? And I'm glad that you asked this because we didn't really talk about tidymodels a whole lot, but carrot was this package to do machine learning and tidymodels, obviously we talked about is this kind of newer version and there is so much good stuff out there. So if anybody out there in the chat also has resources about tidymodels or blog posts that are using tidymodels, please share. I think I have a couple that I can go see, but maybe Max has a couple that he can pull out of his brain.
I mean, nothing with the obvious one. So the tidymodels book is helpful. I need to update it. There's nothing really wrong in it, but there's a lot of additions and changes we've made. And then the book computer that we're writing is not complete, but that's helpful. I mean, if you're just starting with tidymodels, then the tidymodels book is probably the best because it's like long form and really thought out about how we like explain like why it exists and what it's good for. And there's a lot of examples, but if you're like, Hey, I want to fit this type of model. What's the syntax for that? Then if we already have a chapter for that in the current book, we're writing that companion tidymodels.aml for td.org is probably the best.
Okay, great. Well, I will add mine, which is Julia Silge's tidy model section of her blog, where she has several blog posts where she is walking through using tidymodels. I mean, you can scroll through this. She uses tons of tidy Tuesday data. It's very accessible. And of course, Julia Silge is just kind of the goat when it comes to blogging. So definitely go check that out. I put it in the chat. And now I would love to pull in Arsenis. Arsenis, you had a question in Slido. Let's see if we can get you unmuted so you can ask that live and I will highlight it in Slido for everybody. Cool. Thanks, Libby.
Inference vs. prediction
Hey, thanks for joining. I appreciate the time. My question for you is more kind of a trying to get to your statistician brain in terms of how you kind of communicate to folks. And basically, what do you find most challenging or rewarding about writing packages that do both inference and prediction? And kind of a follow up to that is, do you think that that gap is easy to bridge for a lot of folks? Or do you think it's kind of a challenge for most people?
Yeah, that's a really good question. Yes, I tend to think of, I'm trying to, I always try to find analogies to things and maybe I don't need one. But like, if you think about like linear or logistic regression or something, it could function in many, many different levels, right? And so, you know, being my degrees in biostats and like two thirds, if maybe three quarters of my department was really concerned about like inference. And then the other 25%, let's say, are concerned about like estimating stuff. And I definitely am more interested in the 25% of estimation. To me, it's like a more fun problem.
Yeah, I don't know. I find that like, when I think about these things, I either, I start and either just go in left or right in the direction of either inference or prediction. And from there, like the only time I think they sort of like, there's a bridge that goes between them is, and I promise you, I wasn't really obnoxious about this, but I would see a lot of presentations at where I worked, where people were presenting some logistic regression and they, let's say, you know, for something fairly important, they're looking at, you know, model selection. So they're just looking at P-values and what's the right combination of things to, for whatever definition they had of optimal. And, you know, my question was like, what's the accuracy of this model? And they'd be like, you know, like what? And I'm like, well, is it like 50% accurate or like 80% accurate? And like, well, we're not trying to predict. I'm like, yeah, but like, if it doesn't have much fidelity to the data, like we kind of have to calibrate that to know whether these P-values are important. Because if the model is not even good at even a close ballpark prediction, then like, you know, how, I'm not saying like the P-values would be invalid, but at the same time, like you need to know how well does your model emulate what you're modeling? And then, and so just the idea that I just, like the only metric is P-value based always kind of bothered me. I'm not trying to make everything a prediction problem, but like, it's the same thing where the other direction where people like, you'll choose like, oh, I should use this many splits in a tree versus those many splits. And somebody would say like, well, they're not really statistically different. Like, well, yeah, they're not. So I don't know. I think there is a situation where those things overlap, but more than like in a diagnostic sense.
So yeah, I don't know if that answers your question or not. That's, I mean, that's probably the challenge is making sure you know the right sort of like mode that somebody's in for their analysis and making sure you like talk about it and frame the problem in the right way. Because if I come out everything from a prediction standpoint, then there's no, if you're an inference person, you're like, what is this person talking about? That's not how I'm thinking about it. It is kind of weird that we have these different like ways to just evaluate models based on how they're being used. I mean, maybe it's not weird, but they're just so far apart from one another that it's sometimes hard to reconcile. When maybe they shouldn't be. Yeah. I kind of, I'm kind of on your team about this, but I also know that there's like probably some Bayesians listening who are like screaming, oh, Bayesian is the answer to that problem.
Oh, I am 100% down that. Yes. I, when I was in drug discovery, our director said, and a lot of people like revolted about this, like every analysis has to be Bayesian and I get where he was coming from. And, but any sort of inferential stuff I do now, it's Bayes all the way down for
me. Like I am completely down. You heard it here first folks. Okay. Well, we have seven minutes left and I would love to take this opportunity to ask you the question that we try to ask everybody, which is, do you have a piece of career advice that you find meaningful, was helpful for you or something you wished you knew before you kind of got into the space you're in?
I don't know that I'm even qualified to answer this because my career started in like 1998. So like I'm not a young man. So like, I feel like everything's different now. But I do talk to, I have a lot of friends whose kids are going to graduate school and a fair amount of them are interested in statistics. And, and it surprises me sometimes because I feel like, I feel like we're viewed as these rare and arcane wizards that like, are the only people who know how to kill the dragon. But everybody's afraid to approach us because they're like, don't smite me. Like just by asking a question.
I feel like this might be obvious, but the more people I talk to, maybe it's not. Because we're like, often deep in especially open source software and things like that. But like, talking to talking to a friend's kid, and I was basically saying like, put as much out there on GitHub of yourself as you can. Even even if you know, having something concrete, you can point to that you did, and there's like commits, and things like that. Even if it's not groundbreaking, and it's like, you're just analyzing the Ames housing data or whatnot, like have something that kind of acts as your portfolio.
And, and for me, it's like, having both been a hiring manager of statisticians and data scientists and somebody who, you know, almost every year is trying to hire interns, the thing, you know, we get a lot of CVs that just say, Oh, I did this. And I did that. And it's like a few sentences. And I know some of it, like you can't talk about, especially if you did work company, but you know, I would absolutely try to convince people to do something. It doesn't have the bar is really low, but have something of decent quality. Like, you know, it's not like RM, LS, list equals type code, but like, you know, like a shiny app or something that you can just show people and point to that you did. And you can look at my code and, you know, look that I know how to make commits or whatnot. I feel like that is the number one thing you can do. And honestly, when we, when we go to hire people, even pre AI, that would will it down to like 10% of the people who apply that I can actually see that you've you know, something you've touched code. It's not like we don't believe people. It's just like seeing it is incredibly helpful and trying to figure things out.
And honestly, when we, when we go to hire people, even pre AI, that would will it down to like 10% of the people who apply that I can actually see that you've you know, something you've touched code. It's not like we don't believe people. It's just like seeing it is incredibly helpful and trying to figure things out.
Now, the problem we have now is everybody just like, like we have, I shouldn't say this, but like, you know, when we, we have people apply to internship jobs, for example, like we have to have their GitHub user ID, because they're going to need a GitHub ID. So we asked for it. And if they do it, like, you know, and they have a bunch of tiny model stuff, I'll look to see if it was like, you know, started the week after the position was like announced, which isn't bad, because they're showing interest. But like, like, it's really easy for recruiters and things like that, that could. Yeah, I know, right? I shouldn't say this. It's really easy for anybody to just, you know, parse this data and look at it. So it's really important to just have something out there showing your interest in something, showing that like, you know how to code or do stuff, even if it's like, even like stat or something like that, just put something out in public that somebody can see it. And do as much of that as you can.
Career advice and building a public portfolio
Round of applause. Absolutely. I think the most important thing that Max just said is that out of all the people who apply, it can whittle it down to 10%. That means that if you do the thing, and you talk about it, write about it, put it on the internet, you are automatically putting yourself in the top 10% of candidates for something. Think about that. There's 1000s of people doing the thing. If you're the one who talks about the thing, doesn't matter if you're the brightest, sharpest tool in the shed, best at it, whatever, you are automatically giving yourself a leg up. I highly encourage you to do that. Make a Quarto website and put some freaking Quarto documents up there with your analyses. And it doesn't even matter if they're right, but you can write about what you think about them, what you learned about them. And there's so much data out there, you will find something that's, even if you've done something that's really cool, you can't talk about, you can find something that you can do parallel to that, that would demonstrate.
That's close. Yeah, you can talk about it. And Max also mentioned, maybe don't just have rmlist equals ls at the top of every script. But also, I'm pretty sure I had that in my first bunch of stuff that I put on the internet. It's like, no, I will never look at this person. It's not good, but at the same time, that's what we come to expect, especially from internship positions. Yep, yep, yep, yep. Don't be afraid. Don't be afraid. All right. I think that's fantastic advice. And in our two minutes left here, I want to say thank you, Max, for joining us. This was a lot of fun.
Community building in data science
And also, Max also mentioned something that I love, which was with the JoCo crew stuff. He was like, you get to go be part of a community with these people that are a lot like you and that you also revere and are just normal people like you and kind of get to be in this pool of people. Joining a community, starting a community can be such a transformative thing for your life. And it can happen in data science, too. I feel like it has for me. It has for Rachel. And I want you to, if you would like to start a data science community at your work, because that is also transformative for your work, for your team, for the work that you do, we are having a community building panel. It's separate from the Hangout. It's on August 5th, I believe, at the same time that the Hangout is, so 12 p.m. Eastern. And we're going to have guests from three different industries join us and talk about how having an internal data science community at their company helped innovation and helped their sense of morale and community and culture.
You all know that I'm really excited about this. If you would like to also be a community builder in the data science space within your own organization or your field, whatever, please come join us. Hang out with us. Rachel can put stuff in the chat for how to join that. And also, I think we have a blog post out where you can learn a little bit more about the steps that we have learned that you can take to build community. And if you see me out in the wild talking about this, I'd love it. It's my favorite topic.
All right. That's it for me. I just shared the links there and I shared the link to the blog that Libby and I wrote about starting your own Hangout at your company, too. But I also wanted to say, like, it doesn't just have to be if it's at your company or organization. Yeah. Also, we're seeing a resurgence of some in-person data science meetups. And so we would love to talk to organizers of those meetups all over the world as well. So I hope you'll join us for that. Yes, yes, yes. Let us know how we can give you tips to make things work smoother for you, to make you feel less overwhelmed. And maybe someday we'll have a JoCo Cruise that's all just our programmers. It'll be our cruise. They know who we are. They know who we are. It'll be the nerdiest. It'll be the nerdiest.
Well, I love this. This was so much fun. My only regret is that we did not veer into Cosmere territory, Max. But we are at the top of the hour. If you want to talk about the Cosmere with me or Max, find us on Blue Sky and talk to us about it. All right, everybody. This was fantastic. Welcome back. After two weeks being off, this was so fun. I am so glad that I get to spend this time with you every week. And we will see you next week, where we are joined by our very own Hubert Hickman. And we get to learn a lot more about him. You have heard him ask questions for months and months on The Hangout. And he's so much fun, so we can't wait to talk with him. Goodbye, everybody.